Jeff Dean and Fei‑Fei Li’s latest talk: All RSI, no consensus
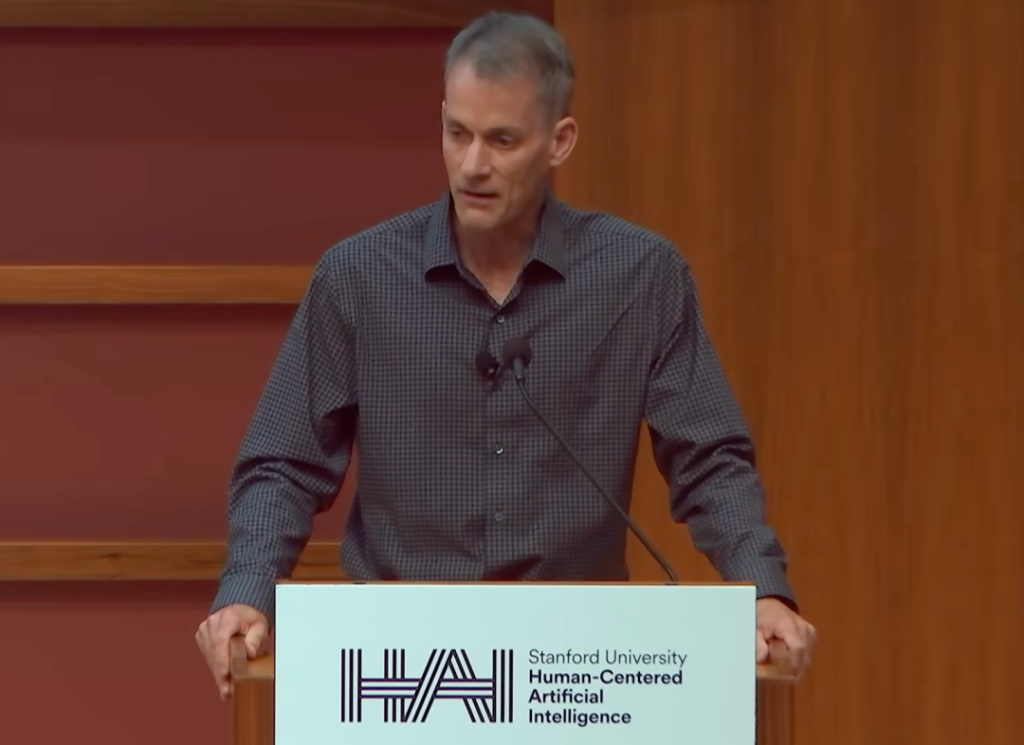
Jeff Dean and Fei-Fei Li’s Latest Dialogue: All RSI Non-Consensus
Content Summary
Ting Yu posted from Ao Fei Temple Qbit | Official Account QbitAI. RSI is so popular, can it really make AI’s progress speed infinite? Jeff Dean’s assessment: not very realistic. He gave an example: a person
Ting Yu posted from Ao Fei Temple
Qbit | Official Account QbitAI
RSI is so popular—can it really make AI’s progress speed infinite?
Jeff Dean’s assessment is: not very realistic.
He gave an example: a person starts an experiment, it finishes at 2 a.m., and he has to wait until 8 a.m. back at his desk to check the results.
An automated system can eliminate this waiting period and promptly decide what to do in the next round. However, training, computation, data storage, and result evaluation still take time.
To build a foundational model and improve it, a large amount of training and experimentation is still required,these processes cannot be completed at an infinitely fast speed.
Recently, in a conversation at Stanford HAI(Human-Centered AI Institute) with Fei‑Fei Li, Jeff Dean discussed the limitations of RSI and also disclosed what his new company is working on.
The whole thing still has that ultra‑minimalist PPT vibe of Google’s brother‑in‑law…
According to him, the new company Discovery Loop already has about 20 automated improvement loops running, and has also built a collaborative framework that supports humans and agents working together.
They want a small number of experts to lead many agents in research, aiming to boost domain experts’ productivity by 20 to 50 times.
To build this team, in the first three weeks they conducted 400 interviews in places like cafés.
He also revealed that a co‑author of the Kimi K3 paper, who is also the author of the Attention Residuals work, has recently joined the company.
This new colleague should be 17‑year‑old Chen Guangyu.
When discussing the technologies that underpin these changes, Jeff Dean also admits that he missed the mark on some things.
One of them is programming.
In the Gemini project, programming was originally one of the team’s focus areas. However, he did not fully anticipate that this capability would so profoundly affect the model’s ability to solve various problems.
He also once expected neural networks to develop more exotic, irregular structures, and this evolutionary path did not unfold exactly as he imagined.
When it comes to AI doing mathematics, he acknowledges the value of machine‑generated proofs, but he places greater importance on whether humans can understand and distill from these results methods that can be used further.
The following is a polished Chinese summary of the talk and discussion.
Enjoy~
Jeff Dean Keynote: AI Runs Experiments on Its Own, Aiming to Boost Expert Productivity by 20–50×
Automate the experimental cycle
I’m glad to be with everyone today. I will introduce Discovery Loop.
Our mission is to build AI systems that automatically solve important problems in machine learning, science, and engineering.
We believe this will ultimately lead to more discoveries, which is what excites us.
Many disciplines share a common process that can be called the universal cycle of science and engineering: propose an experiment, implement and run it, observe the results, examine the measurement data, and then decide what to do next. The next step is often to run another experiment.
Our approach is to automate these experimental cycles.We believe that by shortening the time of each iteration, automatically generating and running a large number of experiments, and learning from each evaluation so that subsequent experiments can build on previous results while increasing both the quality and quantity of experiments, we will achieve breakthrough outcomes.
This is what we want to do.
Take a look at this list of Grand Challenges from the US National Academy of Engineering. These are important problems that need to be solved in the 21st century, and about a quarter of the century has already passed.
Consider what sub‑problems need to be tackled to solve them, especially the areas highlighted in red in the diagram; we believe an automated discovery loop can help.
Why Establish a Public‑Welfare Company
One point is very important to us, and it’s part of why we founded an independent company: if applied correctly, technology can have a huge positive impact on the world, but it requires collective effort to ensure that impact materializes.
Therefore, we established the company as Public Benefit Corporation, that is, Public Benefit Corporation.
Our public mission is to develop technologies that address important social issues, enabling more people to benefit from these technologies and improving lives.
The Experiences of the Four Founders
A brief introduction of the four of us. My three co‑founders are Sanjay Ghemawat, Quoc Le and Oriol Vinyals.
Based on our pairwise collaborations, we have worked together for 14 to 30 years. We enjoy tackling challenges together and have accumulated experience in various areas.
We all come from Google, so the work showcased here is all related to Google. We have worked on multiple generations of search products, early advertising systems, content ads, as well as products like Gmail, News, and Translate.
The second column is infrastructure. The upper portion of the system helps people organize and manage massive amounts of data, run large‑scale computations, and extract valuable insights.
The four items below are multi‑generation, large‑scale machine‑learning infrastructures used to train increasingly capable models. We have also been involved with TPU, a dedicated hardware platform for machine learning.
In AI research, we have contributed to many key technologies behind today’s high‑capability models, including model distillation, mixture‑of‑experts (MoE) models, and neural architecture search.
Neural Architecture Search can be seen as an early form of an automated experimental loop: searching for neural network architectures suitable for solving a particular class of problems.
We have also worked on AI applications in various fields, including scientific research. Quoc and I participated in AlphaChip, using reinforcement learning for chip design, including placement and routing.
Oriol has worked on AlphaFold and neural network weather forecasting. We have a strong complementary experience.
We have also managed very large teams. The Google Brain team I led had up to 600 members, and the Google Research and AI teams had up to about 4,400 members.
Later I realized I was spending too much time in meetings discussing Q2 operating expenses. I hit the send button on an email and reduced my management scope from 4,400 people to just four direct reports.
In the following week, Geoff Hinton retired, so I was left with only three reporting lines.
Later, Oriol and I jointly served as technical leads for the Gemini project, while Quoc handled post‑training.
We’re also proud of those who once worked on the team and later achieved outstanding results, including founders of companies such as Anthropic, OpenAI, and Physical Intelligence. Physical Intelligence should be quite well‑known at Stanford.
Our expertise combines AI research and distributed systems.
This chart lists some highly cited researchers in AI and distributed systems based on Google Scholar citations; we are highlighted in the red box, and those marked with an asterisk have also worked on our team.
Team Building and Recruitment
We have a great time together and have visited many places. The photos include London, Patagonia, Vietnam, and California.
Quoc and I once finished dinner and took an Uber-like motorcycle service back to our lodging.
In the first stage after the company’s founding, we devoted a lot of effort to building the founding team. Everyone comes from different places, as you can see from the logos in the picture. Many have experience founding companies or leading major projects.
The team includes experience leading Go language projects as well as key contributors to Gemini, DeepSeek, Kimi K3, and other projects. One co‑author of the Kimi K3 paper, who also authored the Attention Residuals work, recently joined us.
〔Note: This should refer to Chen Guangyu, Kimi researcher before age 17.
Our team includes both seasoned professionals and rising stars early in their careers. About 10% of the company have received ACM Computing Awards, and another 10% have earned medals in the International Olympiad in Informatics (IOI).
We look forward to working with these individuals and place great value on our ability to collaborate together.
Why we can do this now
Why now? Because cutting‑edge models have become extremely capable. This stems from innovations across multiple facets of AI over the past 10–15 years.
Hardware performance has greatly improved, including TPUs, GPUs, and other more specialized hardware. Software abstractions have also been refined, making it easier for people to implement what they want and map computations more efficiently onto hardware.
Model architectures are also evolving, such as word2vec, sequence-to-sequence models, Transformers, and MoE. Training algorithms have made many advances, and techniques like distillation enable smaller models to achieve good performance.
Inference algorithms have also improved significantly. We can allocate more computation during inference to obtain better results, such as using chain-of-thought, or trying multiple solution methods and then checking the outcomes.
Models need tools, creativity, and experience accumulation
A powerful base model alone is not enough to solve the problems we want to tackle. Starting from an excellent base model, we need to integrate agents so the system can effectively use tools and accomplish complex tasks.
We especially hope that agents and models possess creativity. Breakthroughs in science or engineering often require combining different insights, proposing something new, and then testing its effectiveness.
These systems should also learn from past experiments and experiences. This includes learning from solving current problems as well as long‑term accumulation.
Assuming a system has already solved 5,000 problems, when it faces the 5,001st problem it can draw on the experiences most relevant to the new problem.
The difficulty of large projects also lies in division of labor and coordination
Each stage of the traditional experimental cycle requires a lot of manual labor.
When dealing with larger problems, things become more complex because you usually have to break them down into many sub‑problems or sub‑modules, and the decomposition itself is a challenge.
In each sub‑field, many people run experiments to determine which methods work and which don’t.
This leads to coordination overhead, resource conflicts, and large‑scale system‑level issues. Decomposing the problem is difficult, and integrating the results of each sub‑problem is also challenging.
The more troublesome part is that once a large project gets underway, the original decomposition approach is hard to change. Whether it’s building an aircraft or training cutting‑edge models, early decisions become difficult to adjust flexibly.
We believe that a small number of domain experts can work together with automated systems. Ideally, the system would automatically break down worthwhile research sub‑problems and solve them autonomously.
Of course, it may also require someone to guide the decomposition and determine which sub‑questions are most important.
In this way, a small number of domain experts can tackle large, high‑impact problems. We believe that the right infrastructure can support this way of working.
You need to run tens of thousands of automated experiments, and you also need the system to understand the value of different experiments and decide what to do next.
Reinforcement learning or evolutionary algorithms can be used for automated decision-making, making previous decisions easier to reassess. Every early experiment should provide information for subsequent experiments.
Approximately 20 automated improvement loops are currently running
What are we doing right now?
In the first three weeks, we conducted 400 interviews, mostly at Cafe Venetia on University Avenue, looking for the talent mentioned earlier.
We are also looking for office space, and have now moved into the former location of the Zibibbo restaurant; the space has a distinctive character.
We have built our own intelligent agent runtime framework, the agent harness, for internal development and automation.
It has some great collaboration features: you can converse with the model, ask it to solve problems, and you can also invite colleagues to join, allowing two people to interact with the model and agents together.
Others can comment on the work in progress and provide design feedback before the plan is handed over to the agent.
Our infrastructure has been built from the start to serve agents, with the goal of scaling to tens of thousands—or even hundreds of thousands—of agents executing tasks, not just supporting a few hundred human workers. We consider this crucial.
There are now about 20 automated improvement loops running, and we can see them operating and improving.
We are also evaluating how to make these experiment iterations more effective and faster, and how to leverage previous experiment results and measurement data to accelerate system learning.
The goal is to increase domain experts’ productivity by 20 to 50 times
This is our current state: building software loops, automating machine learning tasks, because we believe this can drive more autonomous scientific research.
Initially, we focused on building automated systems that could address machine learning research and engineering problems.
Our goal is to increase domain experts’ productivity by 20 to 50 times.
We hope that these domain experts, as well as those truly intent on solving a particular problem, can resolve issues with less effort. Humans still have their own role in the process.
The breakthroughs in machine learning over the past 15 years have produced powerful models and paved the way for automated machine learning, science, and engineering, thereby accelerating the pace of discovery. Thank you all.
By the way, we are hiring; you can apply at discoveryloop.com.
Jeff Dean talks with Fei‑Fei Li: RSI also has physical limits, and the distillation paper was once dismissed as having no impact
Why Leave Google to Start a Business
Fei‑Fei Li:Thank you Jeff, that was a great talk. I think this should be the last one, and we’re right between the audience and the refreshments.
Jeff Dean:It has never been a good spot.
Fei-Fei Li:I originally hoped this discussion would be more technical. However, since it’s a dialogue, I will both ask questions and take part in the discussion.
Thank you for your talk, my first question was actually: Why start Discovery Loop? Congratulations.
Jeff Dean:Thank you.
Fei‑Fei Li:The four of you have basically worked at Google for a long time, especially you, who joined Google in 1999.
The technological advances of recent years have been evident to everyone, but I’m still curious—has there been a moment, perhaps in the past year or two, when you, Quoc, Sanjay, and Oriol felt that you had to do something different and that it required leaving Google to do it?
Jeff Dean:We have been excited to see that automation systems are increasingly helping people develop software.
Quoc did a lot of neural architecture search work ten years ago; you can think of it as an early recursive self‑improvement system: letting it search for model architectures suitable for computer vision or language tasks.
We know these methods work. However, back then you had to use a bunch of messy Python code to define the search space.
Now you can make requests in natural language to a capable model and agent system, such as exploring model architectures that help interpret MRI images, and then have it carry out the work.
This changes our imagination of what computers and AI systems can do. If we can make these systems operate reliably, many things become possible. We believe that science and engineering are especially well‑suited to generate positive impact through this.
李飞飞:So what gives you the entrepreneurial ideas is these cycles and self‑improvement capabilities.
Jeff Dean:Someone might say we’re a bit “loopy”.
[Note: This uses a pun on “loopy” and “loop,” carrying a slightly crazy, quirky humorous nuance.]
Jeff Dean:There’s also another important point. We’ve gone through the process of starting from a very small project many times, and we love that feeling: it starts with five people, then a sixth, a seventh, a tenth—it’s really fun.
Even in a large company you can have experiences like this. But we want to turn it into a public‑benefit company because that reflects our values.
Entrepreneurship also means bigger challenges—you have to handle office space and other matters involved in setting up a company, which is also fun.
李飞飞:I also had a similar tech moment when I founded World Labs.
Our focus differs from yours; what drives us is the fusion of computer vision and generative models, which shows us the possibility of creating generative models that go beyond text.
Jeff Dean:The generative models you have created, and the capabilities you can achieve now, are indeed impressive.
How to Distinguish Self-Improvement from Recursive Self-Improvement
Fei-Fei Li:Let’s talk about self-improvement and recursive self-improvement, going a bit deeper. We grew up learning machine learning around the same time.
I was just thinking about how many names this concept has gone through: incremental learning, continual learning, meta‑learning, lifelong learning, neural architecture search, and now self‑improvement and RSI.
Could you give the audience, especially those with a technical background, a more precise definition?What is self‑improvement, and what is recursive self‑improvement?I want to separate imagination from fact.
Jeff Dean:The loop I described earlier can be applied to many problems. My understanding of a self-improving system is that you give it a goal, usually a measurable metric such as the accuracy of a machine‑learning model. The system then tries different model architectures to improve that metric.
Fei‑Fei Li:Hold on a moment, many machine learning algorithms can already do this.
Jeff Dean:Right.
Fei‑Fei Li:This itself isn’t recursion, right?
Jeff Dean:For example, we give the system a batch of magnetic resonance imaging (MRI) data and corresponding results, asking it to develop a model that helps interpret these medical images. The system can automatically develop models, try different approaches, and we expect the accuracy to improve as the experiments progress.
But this does not improve the underlying system responsible for proposing the next experimental plan.
Recursive self‑improvement is about: how to apply the same self‑improvement methods to the underlying system that is responsible for generating the improvement proposals itself.
Why can’t the self-improvement loop run infinitely fast
Fei‑Fei Li:I understand. But this concept is easily confusing for many people. Especially in Silicon Valley, people use it very casually, and as a scientist, that makes me a bit uncomfortable. I hope to define RSI clearly here.
Let’s discuss the physical limits of RSI again. It is now described as a system with no end, capable of accelerating indefinitely toward infinity. Which parts are hype, and which are imagination?
Jeff Dean:Think about the past 10 to 15 years and how humanity has improved model capabilities: researchers and machine‑learning engineers conduct a large number of small‑scale experiments together, distinguishing which ideas work and which don’t, and then apply the successful methods to the next generation of models.
After Gemini 1 came Gemini 2, just like that.
This is a normal research and engineering process. With automation, some steps can indeed be sped up. For example, if someone starts an experiment that finishes at 2 AM, they have to wait until 8 AM back at their desk to check the results.
The automation system can promptly view results and determine what to do next. It can also make better judgments at the level of an entire large project than individuals making separate decisions about the next steps.
But building a base model and improving it still requires extensive training and experimentation, and these processes cannot be completed at an infinitely fast speed.
Here is a real physical process: the computer needs to perform calculations, the results need to be checked, the data needs to be saved, and another model must analyze the results before deciding the next step.
Some people think this loop can run infinitely fast, but I find that unrealistic. We need to stay grounded in reality. Automation systems will certainly speed up the improvement of these systems, but they won’t make them infinitely fast.
Are humans also recursively self-improving?
Fei‑Fei Li:I think this is very important. Actually I didn’t apply for the Discovery Loop position, but I did have coffee with Jeff at Cafe Venetia.
Jeff Dean:We drink coffee for many reasons, because we like coffee.
Fei‑Fei Li:We’ve been talking about the hype versus the facts of RSI, and it looks like we were already preparing for this discussion back then. I came up with an analogy you haven’t heard before—you can agree with it or disagree.
Are humans self‑improving systems, or recursively self‑improving systems? I think humans will definitely self‑improve.
My cooking skills are poor; the first time I make an omelette I might burn everything, the second time I’ll learn from experience and it’ll be a bit better. After maybe ten attempts, I can make an omelette that I can barely eat, but my child refuses to eat.
This is self‑improvement.
But recursive self‑improvement involves the brain. While learning to make an omelet, my brain must undergo some change, neural connections need to be adjusted, giving me a better system to accomplish the task.
If we discuss hardware improvements, maybe I could grow a sixth finger.
Jeff Dean:Maybe you were generated by AI.
Fei‑Fei Li:That’s right. Keep making omelettes, and the brain improves further. If such a loop occurs, humans are an RSI system. Is this analogy correct?
Jeff Dean:I think both apply. People learn many things throughout life, such as making omelets and solving calculus problems; this is self‑improvement. People also learn how to learn.
Fei‑Fei Li:Learning how to learn enables recursive self‑improvement. Once you understand how you receive knowledge and information most effectively, you can learn more things faster.
Jeff Dean:Right.
李飞飞:Recursive self-improvement could also be an evolutionary algorithm, right? Let’s not go deeper for now. I think it’s rare to be able to discuss this issue openly, because there’s just too much hype surrounding it right now.
Jeff Dean:There are many claims that it will be infinitely fast, which is frightening. If you think of it as a running engineering system, the fear lessens and it becomes easier to understand.
First conduct research in the digital environment, healthcare is the future direction
Fei‑Fei Li:You talked a lot about the Discovery Loop, but it’s still a bit vague what scientific problems it actually aims to solve.
I’d like to follow up, within the limits you’re willing to share: among all the scientific questions that can benefit society, which one do you most want to research right now?
Jeff Dean:I have long been interested in the application of AI in the healthcare sector. We will work on it in the future, but not now. This field is important and aligns well with our mission as a public‑benefit company.
Currently, we focus on scientific and engineering problems that can be completed entirely within a digital environment throughout the experimental cycle. These types of problems are better suited for accelerating the whole cycle.
If physical experiments or other real-world processes are involved, speeding up becomes even more difficult. Of course, many important disciplines require physical processes, and we also have some hybrid methods that can help accelerate research in these areas.
Initially, we focused on three areas: machine learning research, machine learning engineering, and hardware design. Concentrating on a few domains makes sense—we have experience in these directions, and this work can help enable other research.
For example, if a system can automatically solve machine‑learning engineering tasks, it can be applied to fields such as healthcare and materials science to develop models tailored to a specific task. This is self‑improvement, not recursive self‑improvement.
We are currently focusing on these three areas and hope to expand into more directions in the future.
Can an automated experimentation system conduct theoretical research
Fei‑Fei Li:I studied physics as an undergraduate. In physics there is a distinction between experimental research and theoretical research. The loop you drew starts with “propose experiment”; in physics we usually say “formulate a hypothesis”, then conduct experiments and evaluate the results.
Whether recursive or not, these powerful AI agents and self‑improvement loops heavily emphasize forming hypotheses and running experiments in parallel. Does this lean more toward an experimental research path? The process of theoretical discovery seems harder to describe.
Theorists like Newton and Einstein didn’t conduct that many experiments themselves. They read experimental results, but their working style was different. Does your approach tend more toward experimental research?
Jeff Dean:Not necessarily, although it may be slightly leaning that way. But I do think that such systems can also do excellent theoretical research.
You can ask it whether it can propose a theory to explain this data. The system can try repeatedly, searching for a theory that explains the experimental data while being as simple as possible.
Many physicists also pay attention to progress in experimental fields, trying to explain phenomena that people have observed but do not yet understand. I think this is possible, and these disciplines should not be completely separated.
Imagine a system that has conducted 100 million experiments across 100 scientific domains, solving one million problems. It has seen a wide variety of experimental results, knows which methods are effective or ineffective in fields related to future questions, and is likely to gain many insights from this.
These experiences may not have strict disciplinary boundaries like human academic departments. One thing I like about HAI is that it can cross organizational boundaries, allowing people from different fields to communicate.
The value of AI mathematical proofs and the role of elegant solutions
Fei‑Fei Li:So we have to talk about math. While preparing this conversation, I also invited Terence Tao, called him, but he couldn’t come.
Seeing these recent developments, I feel a mix of emotions. First the Navier‑Stokes related work, then over 720 mathematical manuscripts, and yesterday OpenAI released more results on AI solving math problems.
I certainly welcome these discoveries. Mathematics, and those problems that have persisted for centuries or even millennia, are a vital expression of human intelligence. Mathematicians see both solutions and beauty.
Now, we have a completely different mechanism for handling these issues.
I’ve had many conversations with Terence Tao. He recently also talked about “Mathematics 2.0,” discussing which problems AI can help solve.
According to him, there are still some problems beyond AI’s capabilities, especially those that have no known solution or lack data.
What do you think about these changes that have occurred in the field of mathematics over the past few weeks?
Jeff Dean:These models, along with agent systems that enable highly parallel operation of the models, have already demonstrated the ability to solve challenging open mathematical problems. This shows us what is possible today.
I think people sometimes feel dissatisfied, even uneasy, because some proofs are as long as 500 pages of Lean code.
Machines can check them, but people still don’t quite understand how to obtain that result in an elegant, concise way.
Knowing that a problem has been proved or disproved is certainly valuable. But when human mathematicians study a problem, they also develop elegant methods. These methods often become new mathematical tools that can be applied to other problems.
Fei‑Fei Li:Do you mean that new mathematics can only come from elegant solutions?
Jeff Dean:No. What I mean is that an elegant solution often yields a good approach that can be applied to other problems.
In some very long machine‑generated proofs, people may not have seen such a clear and elegant approach.
But knowing that something can be done is also very important.If you know a problem is solvable, people will work harder and may discover another, more elegant solution.
Solving so many problems at once may feel unsettling, but it has now become possible. We need to find ways to harness these capabilities to conduct more mathematical research.
Quiz on the Transformer Paper
Fei-Fei Li:We could talk about many more things. However, I promised to give Jeff a surprise quiz on stage without telling him the questions in advance. It’s okay if he can’t answer, because I don’t even remember them myself.
Jeff Dean:Alright, no pressure.
Fei‑Fei Li:Do you remember what day June 12, 2017 was? No cheating with AI.
Jeff Dean:Is it the day the Transformer paper was posted to arXiv?
Fei‑Fei Li:Awesome, A+! I also need to check to find out which day. Did you read that paper on June 12?
Jeff Dean:No, maybe June 10.
Fei‑Fei Li:Oh, right, you might also need to approve it.
Significant technical advances and unmet architectural expectations
Fei‑Fei Li: Looking back on your career, the four of you have done a lot at Google and across the field. Consider that day as a historic milestone, in a sense the beginning of the generative model era.
In the past roughly nine years, which technologies have been most important to you? Also, be candid about which predictions were right and which were wrong.
Jeff Dean:There are a few standout points. Much of the work we’ve done has led to significant improvements, just like the items listed on the previous slide.
Transformer is a more efficient model architecture for handling these problems. Preserving previous states and accessing them via the attention mechanism is a valuable idea.
Earlier approaches updated a smaller vector at each step and discarded previous states. Compared with earlier models like LSTM, the Transformer can learn more with less computation.
Then comes the distillation work done by Oriol, Geoff Hinton, and me. It was rejected by NeurIPS in 2016, with reviewers saying it was unlikely to have any impact.
〔Note: This refers to the paper co‑authored by Geoffrey Hinton, Oriol Vinyals, and Jeff Dean, “Distilling the Knowledge in a Neural Network”(“Knowledge Distillation in Neural Networks”)〕
Fei‑Fei Li:We should create a website to collect those rejected papers.
Jeff Dean:This paper is perfect to include. We posted it on arXiv, and it now has about 40,000 citations.
Distillation is crucial for building models that are both capable and inference‑efficient. You can let a trained, large, and expensive model act as a teacher to teach a lightweight student model. This metaphor fits well in a university setting.
There are also advances in architecture. I originally thought we would see more exotic neural network designs. MoE splits into a set of experts, then merges, then splits and merges again, learning which experts excel at which tasks.
This is useful: a model can have a large capacity while only activating a small subset for each token or task. Yet it remains very regular. In most architectures, the experts are the same size and converge quickly.
I originally expected to see more irregular, seemingly “organic” networks: some neural activity forming columnar structures, some areas with few but large-scale cross-connections linking distant parts of the network. We haven’t achieved that yet.
李飞飞:When doing neural architecture search, we also thought about these, but we couldn’t implement them later, right?
Jeff Dean:The models obtained through neural architecture search are indeed more irregular than manually designed architectures. Manual designs often consist of layer‑by‑layer stacking with occasional skip connections. Architectures discovered by search can exhibit very unique connection patterns.
Fei‑Fei Li:For example, connect this layer to the 17th layer above and do some weird things.
Jeff Dean:Right.
Fei‑Fei Li:So this is something you predicted incorrectly?
Jeff Dean:I have missed a lot of things in my predictions. This one stands out; I originally thought the architecture would evolve more in that direction.
Underestimating the Importance of Programming Skills
Jeff Dean:Programming ability later proved to be extremely important. I didn’t fully anticipate at the time that it would become a key capability for models to solve many different problems.
Fei‑Fei Li:I agree on this point. We knew it was important to some extent, but we didn’t anticipate the impact would be so profound.
Jeff Dean: In the Gemini project, programming was one of the areas we focused on, but it was not the primary focus at the time.
How to Address the Social Impact of AI
Fei‑Fei Li:Since this is the HAI conference, we have to talk about the H, which stands for Human.
What social impacts brought by AI—such as changes in employment, psychological anxiety, and discussions about human extinction, alignment, and related issues—have you anticipated? What concerns you the most right now?
Jeff Dean:AI is an extremely powerful and versatile technology that impacts virtually every aspect of society. Whether it’s mathematics, programming, image generation, or autonomous driving, it can play a role.
Past technological revolutions have mainly impacted five or ten domains deeply. AI affects even more areas, which makes people excited, concerned, and even fearful.
I, together with several co‑authors, wrote a paper titled “Shaping AI’s Impact on Billions of People”, discussing how AI affects the lives of billions of people.
This is my only paper with a dedicated website, because a co‑author created shapingai.com.
[Note: shapingai.com is a research project website by Jeff Dean and others on the societal impact of AI, exploring how to make AI better serve education, healthcare, science, and other fields.]
We examined seven areas, including employment and the economy, AI scientific research, misinformation and media, among others, and consulted with experts in each field to understand the impacts AI has already had and the changes it may bring. It was a very valuable experience.
What concerns me most is how to maximize AI’s benefits across different sectors while minimizing its potential negative impacts. This requires the involvement of technologists, regulators, policymakers, and the public.
For example, when people’s jobs are affected, they need ways to adapt to new demands, continue to secure paid work, and lead a prosperous life. This is an issue that spans many aspects and requires collective effort to solve.
Advice for Young People
Fei‑Fei Li:The last question. Many people don’t know that you care deeply about the younger generation. We don’t often share the stage; I recall the last time was at the Grace Hopper Conference.
Jeff Dean:You have been going for several years in a row.
李飞飞:Now we are on university campuses, and this generation of students feels anxious about jobs and economic prospects, just like Stanford students.
As an AI pioneer and someone who can see technological shifts early, what would you say to these students who are both anxious and hopeful?
Jeff Dean:I can understand this anxiety. The world is changing rapidly, and planning for a fast‑changing future is indeed difficult.
My advice is to try to understand emerging or soon-to-emerge technologies and learn to apply them to the things you are most passionate about.
You might want to become a doctor, pursue literary creation, or develop software more efficiently. AI can help with all of that.
People still need to decide what we want to do together. You should also figure out what you want to achieve and strive to do your best, including making good use of the various tools that have already emerged.
Fei‑Fei Li: So, in the AI era, human enthusiasm still never goes out of style.Thank you, Jeff.
Jeff Dean:Thank you.
Interview link:
https://www.youtube.com/watch?v=ooGKNwJWdb8&t=1s
One-click Triple Action‘Like’ ‘Share’ ‘Heart’
Feel free to leave your thoughts in the comments!
— End —
🌟 Light Up the Star 🌟
Get MirrorSpeed
Get MirrorSpeed