First public results for real-time video AI are outâtop score only 15, all 37 models failed.
Real-time Video AI’s First Public Scorecard Released! The Highest Score Is Only 15 Points, All 37 Models Completely Failed
Summary
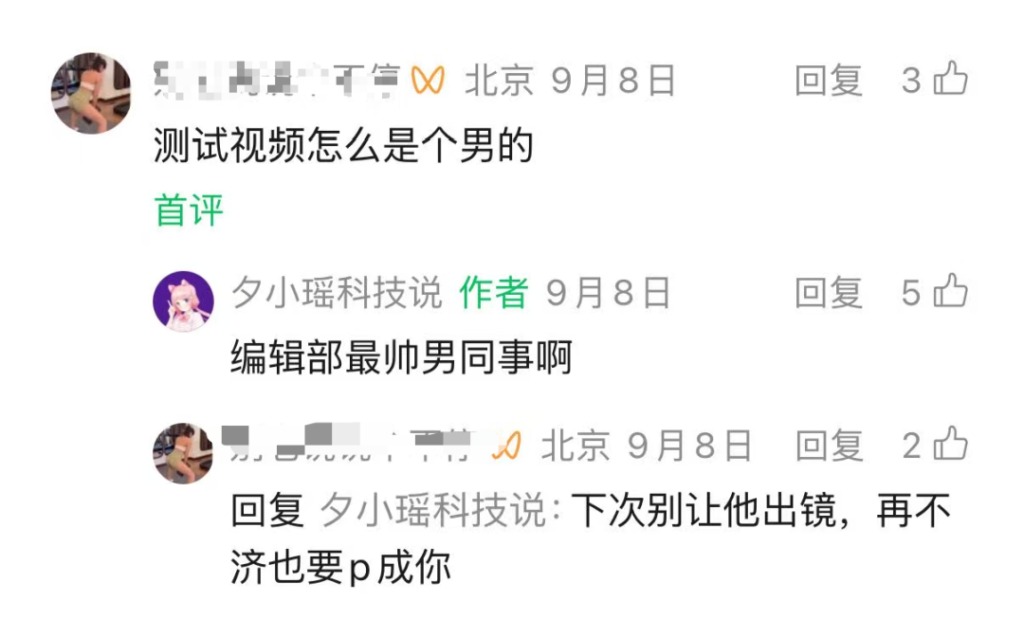
家人们,上次我写摄像头体感交互应用,评论区有位家人问:“测试视频怎么是个男的?”让我们编辑部男同事郁闷了半天,“下次别让他出镜,再不济也要P成你。”满足你!让同
家人们,上次我写摄像头体感交互应用,评论区有位家人问:“测试视频怎么是个男的?”
让我们编辑部男同事郁闷了半天,“下次别让他出镜,再不济也要P成你。”
满足你!
让同事继续负责表演,画面里换成本瑶出镜。
我要撒娇,他也得撒娇;我要飞吻,他也得飞吻。
(Ps:同事负责演,我负责出镜,嘿嘿,编辑部的分工又细了一点。)
怎么样,是不是有点东西!
这件事放在普通的视频生成上,问题其实不大。出来一段视频,好不好看一眼就知道。但实时视频不一样。
它是一条一直往前走的流。你第 10 秒让它换件衣服,第 40 秒又想换回来,第 90 秒说算了还是第一件好看。每插一次话,模型都得同时搞明白三件事:
-
现在要改什么。 -
哪些东西不能动。 -
之前改过的,还算不算数。
那问题就来了:这玩意儿到底怎么测?
总不能截一帧好看的图,就说模型懂我了吧。
然后我发现,这事还真有人认真做了。
◽一张公开的考卷
10 月 20 日,arXiv 上挂出了一篇论文,叫 StreamEval: Evaluating Interactive Streaming Video Generation Models。
论文链接:
https://arxiv.org/abs/2610.28402
看署名,阵容挺硬的:清华、英伟达、CMU、UC Berkeley、普林斯顿、新加坡国立大学,还有 Reactor。
StreamEval,是全球首个⾯向实时交互视频的benchmark。
目前,这个benchmark已经开源,做了一件事:把“实时交互好不好”这件只能靠感觉判断的事,变成公开考卷。
科研机构、企业模型团队、个人开发者能参与:接入模型、复现结果,或者研究案例,把发现的问题+想补的考题直接反馈给维护团队。
代码、案例和评分规则都公开,大家也能反过来讨论:题目出得合理吗,分数判得准吗?这样,模型的进步有据可查,评测本身也能在共同参与中不断完善。
这套基准一共 300 道题,规模不算大,分成五类,每类 60 道:
-
数字人对话 -
数字人表演 -
世界生成 -
文字指令编辑 -
参考图编辑
基本把实时视频现在最火的三个方向都包进去了:数字人、虚拟世界、正在播的视频里的实时修改。
论文一口气测了 37 个模型、47 组组合,前面我玩的那些,换人、换造型,对应的是参考图编辑,“小瑶版”数字人接话、做动作,对应的是数字人对话和表演。
比较有意思的地方,是它的出题方式。
每一道题包括三个元素:
起始素材:人物图、源视频、语音或者参考图。
输入时间线:第几秒,发出哪条新要求。
判卷依据:论文里叫 oracle,写清楚每条要求送达之后,哪里该变,哪里必须保留。
论文中展示了一个非常典型的“披风实时编辑”案例:
这段人物视频的时间线设置是0 秒开始使用“红色丝绒披风”参考图,10 秒切换为“金色缎面披风”参考图,20 秒:取消修改,恢复当前源画面。
这里有一个测试陷阱:
在 20 秒取消修改时,画面恢复的应当是当时时点的源画面,人物与动作绝不能“滚回”到最初起点。
结果,在测试中金色参考图生效阶段抽样的两张输出里,披风依然是原来的灰色——背景和场景虽然保住了,但新外观要求却没有真正换上去。
我也用 Vidu S2 试了试“连续换衣服”:视频里我一直在不停切换第一套、第二套、第三套参考图,而视频流持续往前走。
除了任务类型,题目还按时长分了五档:15 秒、30 秒、60 秒、120 秒、300 秒。
短的看反应快不快、执行到不到位。长的看能不能扛住:要求叠了好几轮之后,它还记不记得前面答应过什么。
◽评测规则
StreamEval 把能力拆成了 4 个维度、10 项指标,每项 0 到 100 分,规则含盖非常全面:
-
任务执行 -
状态一致性 -
视觉保真度 -
声画协调
不同任务只用跟自己相关的指标。
拿参考图编辑来说,它要同时盯三件事:参考图上的样子有没有用上,不该改的地方和原来的动作有没有保住,以及这次编辑到底算不算完整成功。
Ps:所以,在上面换衣服的Case中,即使衣服换对了,但把人物手里原本拿着的杯子给改没了,在 Edit Success 指标下依然算失败!
◽评测方法
评测打分的过程分为两步:
- 视觉语言模型(VLM)
先提取结构化观察(比如某一时刻出现了什么缺陷、外观是否匹配、指定动作是否发生); - 固定规则
结合案例规定的时限和验证窗口,将观察转化为精准分数。
没输出、不支持某项必要操作,直接记零分。
还有一点我一开始没想通,后来觉得特别对:
五类任务各排各的,不合并成一个总榜。
数字人聊天和生成一个虚拟世界,根本不是一回事。硬加在一起啥也说明不了,分开测更有参考意义。
◽37个模型,差距在哪里?
论文公布了各模型的测试成绩:
五类任务中,生数科技的 Vidu S2-Avatar 拿到了数字人对话、表演两项的综合分第一:
S2-Editing 在两类视频编辑中领先:
港大、快手可灵等团队提出的MemFlow,¬则在世界生成中排名第一:
如果我们仔细拆解具体分项,会发现实时视频生成行业目前面临的真实困境:
比如,Vidu S2-Avatar 的表演稳定性是97.25,动作跟随是36.90。
而36.90,已经是这项任务里七个模型的最高分了。。。。
(这其实在我把玩 Vidu S2-Avatar的时候就有感觉到:虽然数字人可以保持得很稳,画面也挺顺,但让它抬手、转头、做指定动作,有很大的改进空间。)
严格编辑(Edit Success)难如登天。。。。
在参考图编辑任务中,考查最严苛的“完整编辑”指标,全场最高得分仅为 15.00 分!
其他没拿到榜首的模型分开看其实也是各有“错位优势”:
- Tavus CVI Full
在对话中的音画同步率领先; - LiveTalk 1.3B
在表演画质上表现最优; - JoyAI-Video-Edit
在指令编辑中能更好地保留原视频中不该改变的内容; - Krea Realtime
虽在世界生成综合分上落后,但其指令跟随得分达到了全场最高的 25.93。
借助StreamEval 基准评估到的这些错位优势数据,具有极高的选型价值:实时试衣最怕哪种失误,聊天角色最依赖哪项能力,都能够回到对应指标和输出记录里看。
◈为什么做一个实时视频生成的benchmark
我认为,StreamEval 对整个行业最大的价值,在于把实时视频生成的“可控性”,从一个抽象的概念变成了一组公开、可复查、可量化的标准。
何时修改、保留什么、如何恢复、怎样计分,从此都有规可循。
氮素,这套基准也确实需要继续验证。
比如自动评分还需与人工判断对照,5分钟的案例之外,还要补充更长会话、复杂场景,以及实际部署中的帧率、时延和成本测试等等。
目前,StreamEval 已公开发布了评测代码、案例时间线、数据集与评分规则,放上链接:
GitHub:
https://github.com/StreamEval/Stream-Eval-Open
Leaderboard:https://streameval.ai
论文:https://arxiv.org/pdf/2610.28402
有模型或 API 开发能力的家人们,可以直接参照 GitHub 仓库的接入文档自己配一下,跑跑看自己的模型能拿多少分。
StreamEval 将长期维护,每月都会评测新增模型和更新后的模型,并在榜单上公布最新测试结果。
企业、科研机构和个人开发者,都可以通过官网“Evaluate your model”入口提交模型信息,也可附上自测结果。结果经审核验证后,将被纳入后续榜单。
随着更多模型和版本加入,今天没接住的一个动作、一次切换,到了下一版,就能再拿出来测。
行业积累下来的,也会是一份份可以接着研究、继续改进的记录。
至于评论区那位家人,作业我先交到这里啦~
下次想看我做什么动作,先问问编辑部那位最帅男同事愿不愿意演hh。
Exactly what you want!
Let the colleague keep performing, but replace the on‑screen presence with Ben Yao.
If I act coquettish, he has to be coquettish too; if I send a kiss, he has to send a kiss too.
(P.S.: The colleague handles the performance, I handle the on‑screen appearance—hehe, the editorial team’s division of labor just got a bit more detailed.)
How’s that, does it have something to it?
This issue isn’t really a problem for ordinary video generation.When a video is produced, you can tell at a glance whether it looks good. But real‑time video is different.
It’s a stream that keeps moving forward. At second 10 you want it to change clothes, at second 40 you want to switch back, at second 90 you decide the first outfit was best. Every time you intervene, the model has to figure out three things simultaneously:
-
What needs to be changed now. -
What must stay unchanged. -
Whether previous changes still count.
So the question arises: how do you even evaluate this thing?
You can’t just grab a nice screenshot and claim the model understands me.
Then I discovered that someone actually took this seriously.
◽A publicly released exam paper
On October 20, a paper titled StreamEval: Evaluating Interactive Streaming Video Generation Models was posted on arXiv.
Paper link:
https://arxiv.org/abs/2610.28402
Look at the authors—an impressive lineup: Tsinghua, NVIDIA, CMU, UC Berkeley, Princeton, National University of Singapore, and Reactor.
StreamEval is the world’s first benchmark for real‑time interactive video.
Currently, this benchmark is open‑source and has done one thing: turned the “real‑time interaction quality,” which could only be judged by feel, into a public test.
Research institutions, corporate model teams, and individual developers can participate: integrate models, reproduce results, or study cases, and directly feed discovered issues and suggested test items back to the maintenance team.
The code, examples, and scoring rules are all public, so everyone can discuss in reverse: Is the problem set reasonable? Are the scores judged accurately? This way, model progress is traceable, and the evaluation itself can be continuously refined through collective participation.
This benchmark consists of 300 questions in total, a modest size, divided into five categories, each with 60 questions:
-
Digital Human Dialogue -
Digital Human Performance -
World Generation -
Text Command Editing -
Reference Image Editing
It basically covers the three hottest real‑time video directions right now: digital humans, virtual worlds, and real‑time modifications of currently streaming video.
The paper tested 37 models and 47 combinations in one go; the earlier experiments I did—changing characters, changing appearances—correspond to reference image editing, while the “Xiaoyao version” digital human responding and performing actions corresponds to digital human dialogue and performance.
The interesting part is its question-posing method.
Each question includes three elements:
Starting material: character image, source video, audio, or reference image.
Input timeline: at which second a new request is issued.
Grading criteria: called “oracle” in the paper, clearly stating after each request what should change and what must be preserved.
The paper presents a very typical “real‑time cape editing” case study:
The timeline of this character video is set to 0 secondsStart using the “Red Velvet Cloak” reference image,10 secondsswitch to the “Gold Satin Cloak” reference image,20 seconds: Cancel the change and restore the current source frame.
There is a test trap here:
When canceling a modification after 20 seconds, the screen should revert to the source frame at that moment; the character and actions must never “roll back” to the original starting point.
As a result, in the test where two outputs were sampled during the golden reference image activation phase, the cape remained its original gray—while the background and scene were preserved, the new appearance requirement was never actually applied.
I also tried “continuous outfit changes” with Vidu S2: in the video I kept switching between the first, second, and third reference images while the video stream kept moving forward.
Besides task type, the challenges are also divided into five duration tiers: 15 seconds, 30 seconds, 60 seconds, 120 seconds, and 300 seconds.
Short ones test how quickly and accurately it reacts; long ones test endurance: after several rounds of requirements, does it still remember what was promised earlier?
◽Evaluation Criteria
StreamEval breaks down capabilities into 4 dimensions and 10 metrics, each scored from 0 to 100, covering the rules comprehensively:
-
Task Execution -
State Consistency -
Visual Fidelity -
Audio-Visual Synchronization
Each task only uses metrics relevant to itself.
Take reference‑image editing as an example: it must simultaneously monitor three things—whether the appearance from the reference image was applied, whether unchanged parts and the original motion were preserved, and whether this edit counts as a complete success.
PS: So, in the clothing‑swap case above, even if the clothing is changed correctly, removing the cup the character was originally holding still counts as a failure under the “Edit Success” metric!
◽Evaluation Method
The scoring process consists of two steps:
- Visual Language Model (VLM)
First extract structured observations (e.g., what defect appears at a certain moment, whether the appearance matches, whether a specified action occurs); - Fixed Rules
Combine the case-specified time limits and validation windows to convert observations into precise scores.
No output, or does not support a required operation, assign zero points directly.
There’s another point I didn’t get at first, but later found it absolutely right:
The five types of tasks are ranked separately, not merged into a single overall leaderboard.
Digital human chat and generating a virtual world are completely different things. Forcing them together explains nothing; testing them separately is more meaningful.
◽37 models, where is the gap?
The paper released the test results of each model:
Among the five task categories, Shengshu Technology’s Vidu S2-Avatar achieved the highest overall score in both digital human dialogue and performance:
S2-Editing leads in two types of video editing:
MemFlow, proposed by teams such as HKU and Kuaishou Keling, ranks first in world generation:
If we carefully break down the specific items, we’ll find the real challenges currently facing the real‑time video generation industry:
For example, Vidu S2‑Avatar’s performance stability is 97.25, and motion following is 36.90.
And 36.90 is already the highest score among the seven models for this task….
(I actually sensed this when I was playing with Vidu S2‑Avatar: although the digital human can stay very stable and the footage looks smooth, there’s a lot of room for improvement when making it raise a hand, turn its head, or perform specific actions.)
Strict editing (Edit Success) is as hard as climbing a mountain…
In the reference image editing task, the strictest “complete editing” metric was evaluated, and the highest score in the entire competition was only 15.00 points!
The other models that didn’t take the top spot also each have their own “misaligned advantages” when looked at separately:
- Tavus CVI Full
Leads in audio‑visual synchronization within dialogues; - LiveTalk 1.3B
Shows the best performance in rendering quality; - JoyAI-Video-Edit
Better preserves content in the original video that should not be altered during instruction editing; - Krea Realtime
Although it lags behind in the overall world generation score, its instruction-following score reached the highest in the venue, 25.93.
With the misaligned advantage data evaluated by the StreamEval benchmark, it offers great value for model selection: you can see which mistakes real‑time virtual fitting fears most, which abilities chat characters rely on most, by referring to the corresponding metrics and output logs.
◈Why create a benchmark for real‑time video generation
I believe StreamEval’s greatest value to the entire industry lies in turning the “controllability” of real‑time video generation from an abstract concept into a set of public, reproducible, quantifiable standards.
When to modify, what to retain, how to recover, how to score—there are now clear guidelines for all of these.
Nitrogen, this benchmark indeed needs further validation.
For example, automatic scoring still needs to be compared with human judgment; beyond the 5‑minute case, we also need to add longer conversations, complex scenarios, as well as frame rate, latency, and cost testing in real deployments.
Currently, StreamEval has publicly released the evaluation code, case timelines, datasets, and scoring rules, with the link posted below:
GitHub:
https://github.com/StreamEval/Stream-Eval-Open
Leaderboard:https://streameval.ai
Paper:https://arxiv.org/pdf/2610.28402
If you have model or API development capabilities, you can directly refer to the GitHub repository’s integration documentation to set it up yourself and see how many points your model can achieve.
StreamEval will be maintained long‑term; each month we will evaluate new and updated models and publish the latest test results on the leaderboard.
Enterprises, research institutions, and individual developers can submit model information through the “Evaluate your model” entry on the official website, and may also attach self‑test results. After review and verification, the results will be included in subsequent rankings.
As more models and versions are added, a move or a switch missed today can be taken out for testing in the next release.
The industry’s accumulated records will also become a series of data that can be further studied and improved.
As for that family member in the comments, I’ll submit the assignment here first~
If you want to see what I’ll do next, ask the editor‑in‑chief’s most handsome male colleague whether he’s willing to act out hh.
Get MirrorSpeed
Get MirrorSpeed