Jeff Dean and Fei‑Fei Li slam RSI: How far does Silicon Valley’s AI self‑evolution hype really go?
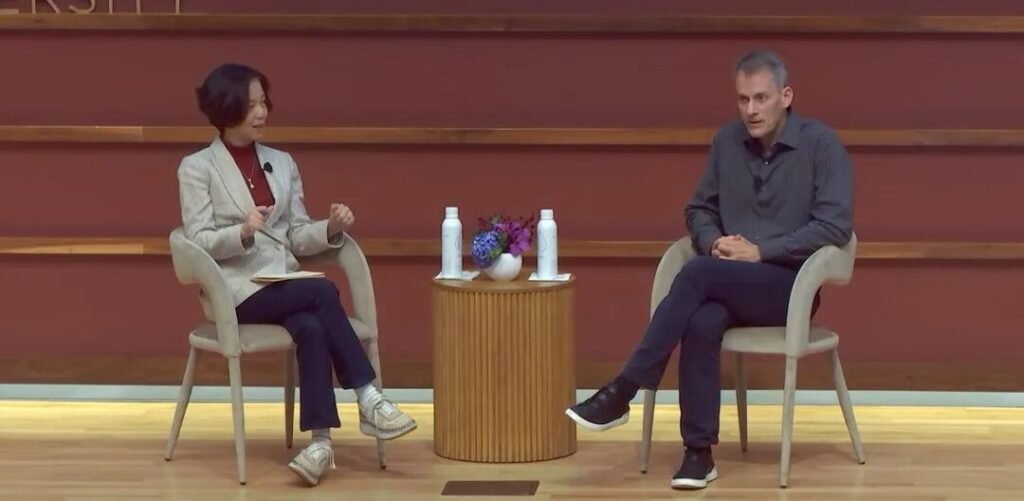
Jeff Dean and Fei-Fei Li pour cold water on RSI: How far does Silicon Valley’s hype about AI self‑evolution really go?
Summary
Editor | Dongmei left Google after 27 years; Jeff Dean bets on AI self‑evolution by starting a new venture after 27 years at Google.
After 27 years at Google, Jeff Dean chose to start a new venture.
This tech veteran, who contributed to major projects such as MapReduce, Bigtable, TensorFlow, TPU, and Gemini, is now turning his attention to an even more challenging direction:enabling AI not only to solve problems but also to design experiments, verify results, and continuously learn from past research.
At a public event of Stanford University’s HAI, Jeff Dean gave the first systematic overview of the technical vision and development progress of the new company Discovery Loop.
Jeff Dean disclosed that the team has attracted researchers from model projects such as Gemini, DeepSeek, and Kimi, as well as members who have contributed to the Go programming language project. In the first three weeks after the company’s founding, they conducted about 400 interviews. According to Jeff Dean’s remarks, roughly 10% of the team members have received ACM Computing Awards, and another ~10% hold International Olympiad in Informatics medals. They aim to bring together senior engineers with long experience in large‑scale AI research and young research talent.
According to his vision, future scientific research may no longer require massive teams to conduct experiments piece by piece. A handful of domain experts could leverage tens of thousands of AI agents to explore different research directions simultaneously, keeping the entire research process running autonomously. This company has already built its own Agent Harness, establishing infrastructure for large‑scale agent collaboration, and is running about 20 automated improvement loops. Jeff Dean set an ambitious goal:to increase domain experts’ productivity by 20 to 50 times.
Jeff Dean has first‑hand experience with the complexity of large technical teams. He once managed a Google team of roughly 600 people, and later oversaw Google Research and AI teams that grew to about 4,400 members.
In his talk, he recalled spending a lot of time in meetings about quarterly operating expenses. He later dramatically reduced the number of people reporting to him by adjusting his work structure.
In the Discovery Loop, he is trying a different approach to research organization. Traditional large engineering projects usually require breaking complex problems down into many sub‑problems and assigning them to different research teams. But this creates new issues: teams need to coordinate resources, experimental results are hard to integrate, and once a project starts, the initial problem decomposition is often difficult to change. Jeff Dean believes that in the future an automated system can take on a substantial portion of the work. A few domain experts define the important research goals, while an AI system automatically identifies worthwhile sub‑problems to solve, organizes experiments, and continuously adjusts direction based on the results.
So far, the Discovery Loop has run about 20 automated improvement cycles, primarily to study how to increase experimental efficiency and how to learn from historical experiment results.
After the talk, a conversation with Stanford professor and World Labs co‑founder Fei‑Fei Li further steered the discussion toward one of Silicon Valley’s hottest and most controversial technical concepts today: RSI (Recursive Self‑Improvement). Can AI truly achieve self‑evolution? Does such evolution have physical limits? When machines begin solving mathematical problems that have eluded humanity for centuries, what role will scientists play?
The two researchers who have been involved in AI development for years offered some rather measured answers.
Below is the transcript of the conversation between Fei‑Fei Li and Jeff Dean, compiled by AI Frontline translators:
Fei-Fei Li: Thank you, Jeff. Your talk was fantastic. I hope the upcoming conversation can dive a bit deeper into technical details.
I will play two roles simultaneously: on one hand asking you questions, and on the other hand participating in the discussion.
First of all, congratulations on founding Discovery Loop. In fact, the first question I originally wanted to ask was: why start this company? All four of you can basically be considered veterans of Google. Especially you, you joined Google back in 1999, right?
In recent years, we’ve witnessed incredible technological advances. Yet I’m still curious—has there been a decisive moment in the past year or two when you, Quoc, Sanjay, and Oriol realized you needed to do something different, and that it couldn’t continue to be done inside Google?
Jeff Dean: I think we’ve always been excited about automation systems, especially technologies that help people develop software systems in a more automated way.
For example, about ten years ago, Quoc had already done a lot of work on neural architecture search. You can think of it as an early recursive self‑improvement system. You told the system, “Please help me find excellent model architectures that can solve computer‑vision problems or language problems.” We already knew at the time that this approach was effective. But back then you had to define the search space with a huge amount of rather clumsy Python code.
Today, you can use natural language directly. You can tell a sufficiently powerful model and agent system, “Please explore some new model architectures and see which ones can help us interpret MRI images.” Then the system can automatically carry out the relevant work.
I think this actually represents a very profound shift in our understanding of computer systems and AI system capabilities. If we can get such systems to run stably and reliably, many new things become possible. Especially in science and engineering, we believe this is a set of research directions that are especially well‑suited for leveraging AI to generate positive societal impact.
Fei-Fei Li: So, what really made you decide is this loop and the ability to self‑improve?
Jeff Dean: You could also say we’re a bit obsessed with these loops. But there’s another very important point. We all enjoy starting from a really small project.When it’s just five people working on something, then a sixth, a seventh, up to the tenth, that feeling is amazing.
This can of course be done inside a large company, but we also want to operate through a nonprofit model. We believe this reflects our values. Of course, entrepreneurship means you also have to handle office space and all sorts of other things, but we find those aspects quite interesting.
Fei-Fei Li: This is fascinating. Actually, when we founded World Labs, we also had a similar pivotal moment. The difference is that the technology direction we focused on was not the same as yours. At that time, we saw computer vision and generative models beginning to merge. We finally were able to build generative models that were no longer limited to text. That was the moment we decided to start World Labs.
Jeff Dean: The generative models you’ve created, and the capabilities that are now possible, are truly impressive.
Fei-Fei Li: Okay, let’s now talk about self‑improvement and recursive self‑improvement. Going a bit deeper into the technology, from the perspective of education and research experience in the machine‑learning field, we’re essentially from the same generation. I was just thinking about how many different names this concept has had since I was a graduate student. We once called it incremental learning, later continual learning, meta‑learning, lifelong learning, and the neural architecture search you mentioned. Now we have self‑improvement and RSI. So, could you give the audience—especially those with a technical background—a more rigorous definition? What exactly is the difference between self‑improvement and recursive self‑improvement? What I really want to do is separate fantasy from fact.
Jeff Dean: I think you can understand it from the loops we just introduced.These loops can be applied to many different types of problems. My understanding of a self‑improving system is that you set a goal for the system and let it improve a measurable metric.. For example, you want to increase the accuracy of a machine‑learning model. The system then tries different model architectures, striving to boost accuracy.
Fei‑Fei Li: Let me interrupt for a moment. Many machine‑learning algorithms can already do this, right?
Jeff Dean: Yes.
Fei-Fei Li: But this itself is not recursive.
Jeff Dean: Absolutely correct. Let me give an example. We feed a batch of MRI images and their corresponding results into the system, then tell it, “I want to develop a model that can help interpret MRI images.” This could be a self‑improving system. It can automatically develop models, try different approaches, and as experiments progress, the model’s accuracy may gradually improve. However, this does not improve the underlying system that is responsible for proposing the next experimental plan. Recursive self‑improvement is different. The key to recursive self‑improvement lies in how to make this self‑improving method, in turn, improve the system that proposes improvement plans itself. I’m not sure if that explanation is clear.
Fei-Fei Li: I understand. But I think, for many people, this is indeed a concept that is very easy to confuse. Especially today, in Silicon Valley, people are using the term RSI very casually. As a scientist, this actually bothers me. So I hope to use this public forum today to clarify the definition of RSI.
Fei‑Fei Li:Next, let’s talk about the physical limits of RSI. Right now, RSI is being hyped as if it were a system with no end. It seems we can keep accelerating it indefinitely, accelerating to infinity. Among these statements, which are hype and which are fantasy?
Jeff Dean: I think, we can first consider how humanity has improved model capabilities over the past 10 to 15 years. We bring together top researchers and machine learning engineers to run a large number of small‑scale experiments. They discover that some ideas don’t work, while others work well. Then we incorporate those effective methods into the next‑generation model. That’s why after Gemini 1, we were able to develop Gemini 2.
Because we conduct a large number of experiments and continuously improve various technologies. This is the normal research and engineering process. When you start automating this process, it can indeed accelerate the pace of improvement. For example, after a researcher launches an experiment, the experiment might finish at 2 a.m., but the researcher doesn’t check the results until 8 a.m. in the office. With an automated system, the results can be examined immediately, and the next steps can be decided in a more automated way. Moreover, from the perspective of an entire large‑scale project, an automation system might coordinate decisions better than each researcher deciding the next experiment individually. However, I think that if you consider how to truly improve foundational models, you’ll find that this requires a huge amount of actual training and experimentation. Those things cannot happen infinitely fast.
Because it involves real physical processes. You have to run computations and look at the results. The computer needs time to perform the calculations. You need to store data, analyze it, and then let another model examine the results to decide what to do next. So some people fantasize that we can make this loop run at infinite speed. I don’t think that idea is credible. Automation will certainly speed up how quickly we improve systems, but it does not mean the improvement speed can grow without bound.
Fei‑Fei Li: This point is very important; we really should bring the discussion back to reality. When I met Jeff at a café earlier, we discussed the hype versus the facts of RSI. However, I haven’t discussed the following issue with you in advance. You may agree, or you may completely disagree.
I’ve been wondering whether humans are a self‑improvement system or an RSI system. I believe we are definitely a self‑improvement system. For example, I’m terrible at cooking. Suppose I try to fry an egg; the first time I might burn everything. But I learn from it. The second time I might do a little better. After trying ten times, I might finally be able to make a passable fried egg. I’m willing to eat it, but my kids might still refuse.
This is self-improvement. However, RSI involves my brain. As I learn to fry eggs, my brain must undergo some change. For example, the connections between neurons change, turning my brain into a system that is better at frying eggs. If we are talking about hardware-level improvements, maybe I could even grow a sixth finger.
Jeff Dean: Then you might be AI-generated.
Fei‑Fei Li: Then, as I keep frying eggs, my brain further improves. If such a loop keeps occurring, are humans essentially an RSI system? Is this analogy correct?
Jeff Dean: I think humans are both. In life, we learn many things. For example, learning how to fry an egg, or how to solve calculus problems. These are forms of self‑improvement. At the same time, we also learn how to learn. Learning how to learn is precisely what gives us the ability for self‑improvement and recursive self‑improvement. Because once you understand what kind of knowledge and what presentation style is easiest for you to absorb, you can use that insight to learn other things more quickly.
Fei‑Fei Li: Yes.In a sense, recursive self‑improvement could also be viewed as an evolutionary algorithm. However, I don’t want to delve too deeply into this issue. I just think that at a time when the concept of RSI is being heavily hyped, being able to discuss this openly is a rare opportunity.
Jeff Dean: Indeed, there’s a lot of hype right now. For example, some people say that systems will improve themselves at an infinitely fast speed, which sounds
scary, but if you treat it as an actual operational engineering system, you’ll find it’s not that frightening and is much easier to understand.
Fei-Fei Li: You just introduced a lot of content about the Discovery Loop. But regarding which scientific questions you actually want to study, it’s still a bit vague. So I’d like to follow up. There are so many important problems in science that can benefit society. Which one are you most interested in right now?
Jeff Dean: For a long time, I’ve been very interested in the application of AI in healthcare. I believe we will definitely conduct research in this direction in the future—not now, but at some later stage—because it’s a critically important field and aligns closely with our mission as a public‑benefit company.
However, at present we mainly focus on scientific and engineering problems that can complete the entire experimental loop in a digital environment. We believe that in these areas the full experimental cycle is the easiest to accelerate. When real physical processes are involved, speeding up the entire loop becomes much more difficult. Of course, many important disciplines must rely on physical processes. We have also considered some hybrid approaches that could help accelerate research in those fields. But for now, we are first concentrating on digitized science and engineering domains.
Specifically, our initial focus includes three areas:machine learning research, machine learning engineering, and hardware design. We think it is more appropriate to concentrate on a few distinct fields rather than trying to tackle everything at once, and these are also areas where we have expertise.
Moreover, we believe these fields are crucial because they can further unlock the potential of other domains.
For example, in the medical and health field, if you have a system that can automatically solve machine‑learning engineering tasks, you could apply it to many problems in medicine, materials science, or other domains. You can tell it, “I want to develop a top‑notch specialized model for this particular task,” and the system will carry out the relevant work. Of course, according to the definition we just gave, this counts as self‑improvement, not necessarily recursive self‑improvement, which is how I describe the company’s current positioning.
We are currently focused on these three areas, but our future goals go far beyond that.
Fei‑Fei Li: My undergraduate training was in physics, and in physics we usually divide researchers into experimental physicists and theoretical physicists. I’ve been thinking about the loop you just showed; you described it as “propose an experiment,” but in physics we usually say “propose a hypothesis,” and then conduct experiments and evaluations.
So, what I want to ask is: as AI agents or self‑improvement loops become increasingly powerful, whether or not they constitute recursive self‑improvement, does this philosophically push us toward a more experimental approach to scientific research?
Because your method emphasizes formulating hypotheses, running parallel experiments, and then evaluating them, rather than a relatively mystical way of theoretical discovery. Even today we still think about great theoretical physicists like Newton and Einstein, who themselves didn’t conduct that many experiments. They read experimental results, but they didn’t rely on an experimental loop for all their discoveries. So, do you think AI is making scientific discovery lean more toward experimentalism?
Jeff Dean: I don’t think the two have to be inherently opposed, but this approach might indeed lean a bit more toward experimentation. However, I believe such systems can also conduct outstanding theoretical research. For example, you could have the system try to propose a theory that explains all existing data. It could iterate continuously, searching for a theoretical description that accounts for experimental results while being as simple as possible.
I think many theoretical physicists conduct their research in this way.
They observe what happens in experimental physics and then try to propose theories that explain phenomena that have been observed but not yet understood. Therefore, I believe this kind of research could very well be carried out by AI systems. In fact, I think theoretical and experimental research should not be seen as completely separate disciplines.
No matter whether it is theoretical physics, experimental physics, or chemistry, they can all be considered within a broader knowledge system. Imagine, if in the future there is a system that has conducted 100 million experiments across 100 scientific fields and solved one million problems.
Then it is likely to accumulate a large amount of valuable insights.
Because it has already observed a wide variety of experimental results and knows, in many similar problems, which methods work and which do not. When you ask it to solve a new problem, it can draw on this cross‑disciplinary experience. I believe this capability is not constrained by strict disciplinary boundaries, whereas humans are sometimes limited by traditional divisions such as university departments.
Fei-Fei Li: Given that, we have to talk about mathematics. In fact, while preparing this conversation, I wanted to invite Terence Tao, also known as Tao Zhexuan. I called him, but he couldn’t make it. In recent weeks, AI has made many advances in mathematical research. From Navier–Stokes related problems, to other mathematical papers, to the results OpenAI just announced yesterday, AI is solving an increasing number of mathematical problems. Frankly, I have mixed feelings about this, of course not because I dislike these new discoveries.
It is not because of mathematics, but because mathematics—and those problems that have existed for hundreds or even thousands of years—have always been one of the pinnacles of human wisdom. For mathematicians, these problems are not only technically significant. They also see beauty in them, and now we have an entirely different machine system that tackles these problems in another way.
Tao Zhe‑Xuan and I have discussed this a lot. He recently gave a talk on “Math 2.0,” describing how AI can help solve certain types of mathematical problems.But he also maintains that there are still some mathematical problems that lie beyond AI’s capabilities. Especially when we have no existing solution and no relevant data. What do you think about this huge shift in the field of mathematics that has occurred over the past few weeks?
Jeff Dean: Clearly, today’s models and the agent systems that can leverage these models for large‑scale parallel work already have the capability to solve some extremely difficult, previously unsolved mathematical problems. This reshapes our understanding of what AI can actually achieve today. But I think the reason people feel somewhat dissatisfied, even uneasy, is that these proofs sometimes involve 500 pages of Lean formalization code.
These proofs have been machine‑checked.But no one truly understands whether there is a concise, elegant way to obtain the same result. Of course, knowing that a proposition has been proved or disproved is a good thing. Yet understanding how to achieve that result with genuinely elegant techniques is equally important. As human mathematicians strive to solve problems, they often develop new mathematical methods, which can then be applied to other types of problems.
Fei-Fei Li: So, you mean that new mathematical results can only arise from elegant solutions?
Jeff Dean: No. What I mean is that elegant solutions often bring a great new technique, which can then be applied to other problems. In some very lengthy machine‑generated proofs, people may not see that clear, elegant technique. But knowing that a problem is solvable is valuable in itself. It’s the same across many fields.
If you know something is possible, you’ll work harder to explore it, because you know a solution does exist.
Then, you might be able to achieve it in a different way, perhaps an even more elegant way. So, I understand why the fact that so many mathematical problems are being solved almost simultaneously makes some people uneasy, but I think this capability has indeed emerged now. Therefore, what people need to consider is how to leverage this capability to further advance mathematical research.
李飞飞:Do you still remember what special significance the date June 12, 2017 has?
Jeff Dean:June 12, 2017? Is that the date the Transformer paper was uploaded to arXiv?
李飞飞:Great! Full marks! I even specifically checked the date. Did you read the Transformer paper on June 12?
Jeff Dean:No, maybe June 10.
Fei-Fei Li: Right, you probably still needed prior approval for that paper at the time. I’d like to use this date to briefly review your career. In the slides you just showed, we can see the massive contributions you four have made at Google and across the AI field. Let’s treat that day as a historically significant starting point. In a sense, it marks the beginning of the generative model era. It’s been almost nine years since then. Looking back on that journey, what do you consider the most important technical moment? Also, I’d like to follow up with another question.I hope you can answer very candidly: over the past years, which things did you predict correctly, and which things did you get wrong?
Jeff Dean: Let me think. Among the many technical advances we’ve made, a few really stand out. First, obviously, the Transformer. For these problems, the Transformer is a far more efficient model architecture. One key idea is to retain the previous states and then access that information via an attention mechanism, rather than, as in the past, updating a small vector at each step and forgetting the earlier information. That’s a very important insight.
Because of that, a wave of progress followed. Compared with earlier LSTM‑based models, the Transformer can learn more with less compute. Another major breakthrough is model distillation. Oriol, Geoffrey Hinton, and I were involved in a distillation study. That paper was rejected by NeurIPS in 2016. The reviewers at the time said the work was unlikely to have much impact. We really should build a site to collect rejected papers—this one is a perfect example.
Later, we posted it on arXiv. Now this paper has been cited about 40,000 times. I believe model distillation is crucial for developing models that are both powerful and highly efficient at inference. You can first train a massive, cumbersome, and expensive model, then let that large model act as a teacher to instruct a more flexible, lightweight student model. Saying it this way in a university setting feels quite apt.
Jeff Dean: The MoE architecture has also proven to be very valuable. But there’s one thing I previously misjudged. I originally thought MoE would herald the rise of many more exotic and diverse model architectures. In an MoE setup, the model assigns tasks to multiple experts and then aggregates the results, then reassigns to different experts and aggregates again. The model gradually learns which experts are best suited for which tasks. This approach is extremely useful; it gives the model a huge capacity while only activating a tiny fraction of parameters for any particular token or task.
However, this architecture is still very regular. For example, most experts have the same scale, and their outputs quickly reconverge. I originally thought we would start seeing a large number of more exotic, more organic neural network architectures—structures resembling neural activity columns, or rare but large-scale connections spanning long distances across the network that could link distant parts together. But so far, we haven’t actually reached that point.
Fei-Fei Li: When we were doing neural architecture search, we also considered similar directions, but those attempts didn’t really meet expectations, right?
Jeff Dean: Yes. In fact, the models obtained through neural architecture search indeed look more organic than human‑designed models. Human‑designed models are usually stacked layer by layer, occasionally adding some skip connections. The networks produced by neural architecture search may contain some very strange connections. For example, a certain layer might connect directly to the 17th layer above it, then perform some special operation.
Fei‑Fei Li: So, is this the one thing you think you predicted wrong?
Jeff Dean: I’ve been wrong about many things, but this one really stands out, because I originally thought model architecture development would move more in that direction. Another thing is that it turns out programming ability is very important for AI’s progress. But I hadn’t truly foreseen that programming would become the key capability enabling models to solve a large variety of different problems.
Fei‑Fei Li: I agree on that. We all know programming ability is important, but we didn’t anticipate it would have such far‑reaching impact.
Jeff Dean: Yes. For example, in the Gemini project, programming is indeed one of the directions we focus on, but it was not the only focus at the time, nor the most central one.
Fei-Fei Li: We just talked a lot about AI’s technical advances, but AI’s impact on society goes far beyond the technology itself. This includes employment issues, people’s psychological anxiety, and now some near‑extreme discussions surrounding existential risk, AI alignment, and similar topics. First, I’d like to ask you: among these issues, which one worries you the most?
Jeff Dean: I believe AI is an extremely powerful and highly versatile technology that is affecting almost every aspect of society. Whether it’s mathematics, programming, image generation, or helping autonomous vehicles drive, AI can play a role. It is different from past technological revolutions. Earlier revolutions usually had a relatively concentrated impact, profoundly changing perhaps five to ten domains. This time, AI is simultaneously influencing a large number of different fields worldwide.
I think this is both exciting and worrisome, even frightening. All kinds of emotions are present. In fact, I once collaborated with a group of outstanding researchers to write a paper titled “Shaping AI’s Impact on Billions of People.” It’s also the only paper of mine that has its own dedicated website, because we had a very creative collaborator who built a site for it: shapingai.com.
In this paper, we examined seven distinct domains, including employment and the economy, AI applications in scientific research, misinformation and disinformation, media, and several other areas. We engaged with a large number of experts from these fields. This was an extremely valuable experience, as it allowed us to understand from their perspective how AI has already impacted their industries and what changes it may bring in the future. But if you ask me what I worry about most, I think the real concern is: how can we maximize the benefits of AI across all these domains while minimizing its potential negative impacts?
Because AI can indeed have negative impacts in many fields, and I believe this is not purely a technical issue. It is both a technical issue and one that regulators and policymakers must confront, as well as an issue each citizen must face. All of us must collectively consider how to harness this new technology, ensuring it truly serves everyone rather than harming humanity in ways we can anticipate. For example, we need to ensure that when people’s jobs are affected by AI, they can find effective ways to adapt to new societal demands. They should still be able to obtain meaningful work, have stable income, and lead prosperous lives. I think this is a problem that spans many different dimensions and requires people from various fields worldwide to work together to solve.
Fei‑Fei Li: One last question. Jeff, I know you care deeply about the younger generation. Frankly, this generation of college students is feeling anxious, even Stanford students are uneasy about job prospects and the future economic outlook. You have such a successful career, are one of the pioneers in AI, and your understanding of future technological developments is often deeper than that of the general public. For the students present today, the young people who are both anxious and possibly hopeful about the future, what parting words do you have?
Jeff Dean: I completely understand this anxiety, because the world is changing rapidly. When you try to plan your own future, if the future itself is changing quickly, making a plan indeed becomes very difficult. So, my usual advice to young people is:
Try to learn which new technologies are emerging, or will emerge soon. Then make sure you know how to leverage these technologies to do the things that truly excite you.
It could be becoming a doctor, or engaging in literary creation, or writing software more efficiently. I believe all these tasks can receive assistance and empowerment from AI. Yet there remains a very important human factor: we humans need to decide what we actually want to accomplish together. As for you personally, you should find what you truly want to do and strive to excel at it. This also means you need to learn to use all the tools currently available.
Fei‑Fei Li: So, even in the AI era, human enthusiasm remains timeless. Thank you, Jeff.
Jeff Dean: Thank you.
Original video link:
https://www.youtube.com/watch?v=ooGKNwJWdb8
Disclaimer: This article is compiled by AI Frontline,does not represent the platform’s views, nor constitutes investment advice, and may not be reproduced without permission.
Heat continues: See you at AICon Beijing in December
On December 18–19, the AICon Global AI Development and Application Conference will be held in Beijing. This year’s conference focuses on exploring the boundaries of AI applications, featuring 13 technical topics that cover core areas such as post-training for large models, inference optimization, agent engineering, knowledge engineering, intelligent agent evaluation and safety, self-evolving systems, AI software delivery, native architecture, and organizational transformation. It brings together frontline technical experts to share breakthrough AI technologies and real-world practices for enterprise-scale deployment.
Today’s Recommended Article
Are you also “watching”? 👇
Get MirrorSpeed
Get MirrorSpeed